2600 Blockchain is a self-sponsored team — Lucas Berretta, Cian Geldenhuys, and I — running an automated arbitrage system on the Polygon proof-of-stake network, built and benchmarked as our UBC Engineering Physics Project Lab (ENPH 459) capstone. The system detects when the same token is mispriced across two or more DEX liquidity pools and captures the spread with a single atomic transaction — one that reverts automatically if the trade is unprofitable by the time it lands. The team had an existing version of this system deployed on Berachain mainnet generating real revenue before this project began.
The prior system sourced all blockchain data from a commercial RPC provider. This was the dominant latency bottleneck: every block notification arrived through at least one extra network hop, and under high load, shared provider infrastructure introduced variable queuing delays that no software optimization could fix. This project replaced that dependency entirely with a self-hosted Polygon full node and a custom Rust block indexer, then measured the result against the provider baseline on live mainnet traffic — no simulated or testnet data.
Background: how DEX pricing works
Traditional exchanges match buyers and sellers through an order book. Decentralized exchanges (DEXs) instead use automated market makers (AMMs): smart contracts that hold two tokens in a liquidity pool and price trades using a fixed formula.
The simplest is the constant-product AMM (Uniswap V2):
x · y = k
where x and y are the reserve balances of the two tokens and k is a constant. A trader depositing Δx of token X receives Δy of token Y:
Δy = y · Δx · (1 − f) / (x + Δx · (1 − f))
where f is the protocol fee (typically 0.3%). The effective exchange rate at any instant is fully determined by the current reserve pair (x, y). This is the key property the indexer exploits: maintaining an accurate copy of every pool’s reserves is sufficient to compute all arbitrage opportunities without any additional on-chain queries at detection time.
Multi-hop arbitrage
Because each DEX operates its own pool for the same token pair, the same token can trade at different prices across pools simultaneously. Atomic arbitrage corrects these discrepancies: a single transaction buys the underpriced token on one pool and sells it on another, reverting automatically if the net result is unprofitable.
For a cycle A → B → C → A across three pools, the trade is profitable when the output of the final swap exceeds the initial input, net of all fees:
∏ [ Rᵢᵒᵘᵗ · (1 − fᵢ) / (Rᵢⁱⁿ + Δᵢ · (1 − fᵢ)) ] · Δᵢₙ > Δᵢₙ
where Rᵢⁱⁿ and Rᵢᵒᵘᵗ are the reserves of the input and output tokens for pool i, and Δᵢ is the trade size at each hop. The indexer’s role is solely to keep reserve values current so this calculation reflects actual market state — Section 6 covers how the live system actually searches for the optimal Δᵢ across an arbitrary number of markets at once, not just a fixed 3-hop cycle.
Why third-party RPC is a structural problem
Most participants access blockchain data through commercial providers such as Alchemy or Infura, which expose a standard JSON-RPC interface from their own servers. This introduces at minimum one additional network hop between the blockchain and the client. Under high network load, shared provider infrastructure adds variable queuing delay on top of that baseline. For an arbitrage system where competitive advantage is measured in milliseconds, these are structural disadvantages that software optimization cannot overcome.
System architecture
Five components form an integrated pipeline from the Polygon peer-to-peer network to on-chain execution, closing in a loop: the execution contracts submit back through the same local node that fed the pipeline in the first place, so the round trip never leaves infrastructure the team controls.
System-level architecture. Blocks arrive from Polygon's P2P network at the local node; the Rust indexer turns them into live pool state; the detection engine and execution contracts close the loop back through that same node.
1. Polygon full node
Deploying a local full node structurally changes how the system receives data. By participating directly in Polygon’s peer-to-peer network, the local Bor client receives new blocks straight from network validators — eliminating the intermediary network hop and delivering block data within milliseconds of creation.
Hardware
The node runs on a dedicated Ubuntu server:
- 64 GB DDR4 RAM — provides headroom for Bor’s PebbleDB state cache, which directly minimizes the latency of RPC calls served to the indexer
- 8 TB NVMe SSD — storage I/O throughput is the binding constraint during initial chain synchronization and ongoing node operation; high-speed NVMe is strictly necessary
Total infrastructure cost came in at roughly CAD $2,850 — an 8 TB NVMe SSD, an HDD enclosure, and networking gear funded by the team, plus RAM and a returned evaluation SSD funded through the UBC ENPH equipment budget.
Client architecture
The Polygon proof-of-stake network requires two coordinating clients:
- Heimdall (v0.6.0) — the consensus layer. Manages validator coordination, span details, and checkpoints block hashes to Ethereum.
- Bor (v2.6.0) — the execution layer. Manages execution-layer state using PebbleDB and exposes a local WebSocket endpoint for the indexer.
Both clients run as isolated systemd services with automatic restart policies and increased system file handle limits (1,048,576) to accommodate PebbleDB’s extensive .sst file generation.
Critical configuration decisions
Client communication protocol: Heimdall and Bor communicate via gRPC on port 9090. The standard REST API on port 1317 is deprecated in Heimdall v0.6.0 — relying on it causes the node to silently stall. This was a non-obvious failure mode that required tracing log output to diagnose.
Network isolation: The node’s network interfaces are deliberately isolated. The RPC server is bound exclusively to localhost, and transaction pool broadcasting is disabled. This ensures the node functions purely as a dedicated data source rather than wasting compute acting as a public network relay.
Bootstrapping: the snapshot problem
Operating a full Polygon node requires downloading and maintaining multiple terabytes of historical chain data. We initially selected Erigon as an alternative execution client — it’s designed to reduce disk footprint through state compression and stateless sync. This approach was abandoned after discovering that the Polygon Erigon ecosystem had severe maintenance deficits: publicly available snapshots were several months out of date, meaning the node would require 1.5 months of continuous operation just to reach chain head.
We reverted to the standard Bor/Heimdall configuration and initialized using a 5.6 TB Stakecraft snapshot, downloaded and extracted via an rclone FUSE mount. The FUSE mount was selected out of necessity: streaming and extracting the archive on-the-fly bypasses local storage constraints, since the 8 TB SSD could not hold both the 5.6 TB compressed file and the extracted data concurrently. The FUSE layer also handles network retries, preventing transient connection drops from terminating the download.
Discovering and patching a corrupted database
During initial latency profiling, we found a recurring ~7,000 ms latency spike exactly every 60 seconds. The subsequent three blocks were sequentially delayed by ~5,000 ms, ~3,000 ms, and ~1,000 ms as the node worked through the accumulated backlog before recovering.
Tracing this to Bor’s block freeze operation: Bor periodically migrates historical blocks from the live PebbleDB to flat ancient files. The downloaded snapshot contained a corrupted block range starting at block 74,592,112 — blocks with headers and bodies but missing transaction receipts. When the freezer hit these blocks, it failed, triggered a database rollback, and held the database lock for ~7 seconds, entirely blocking the indexer pipeline on a 60-second cycle.
Rather than re-syncing from scratch, we wrote a custom Go application that:
- Fetched the missing JSON receipts for the corrupted block range from a public RPC endpoint
- Encoded them into Polygon’s specific PebbleDB storage format
- Injected the encoded bytes directly into the local database
Applying this patch to the corrupted block range allowed the freezer to process the historical data properly, permanently eliminating the latency spikes and stabilizing system performance.
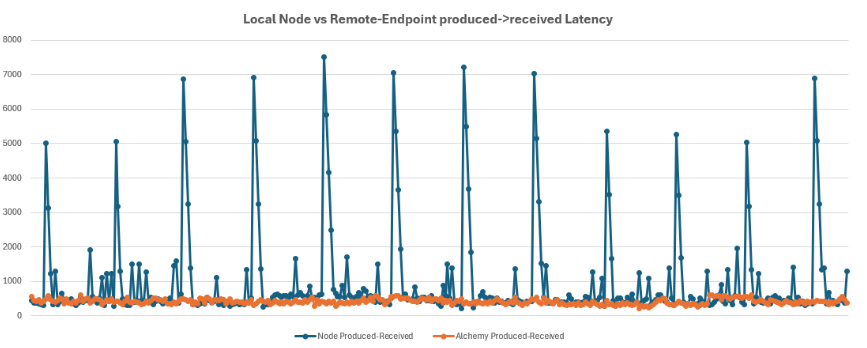
Block produced→received latency before the database patch. The local node (blue) shows periodic ~7,000 ms spikes on a 60-second cycle as the freezer stalls on corrupted receipts; Alchemy (orange) remains flat. After the Go patch the spikes disappear entirely.
2. AMM pool scraper
Before the Rust indexer can maintain real-time state, the system needs to know which pools exist and which are worth tracking. The Polygon network has hundreds of thousands of deployed AMM pools — the vast majority with zero liquidity or negligible trading volume. Tracking every pool would exhaust the indexer’s memory and RPC bandwidth.
This is handled offline by a Python scraper using web3.py and a local SQLite database. Decoupling pool discovery from real-time indexing keeps the latency-critical Rust application free from historical blockchain queries.
Phase 1: incremental pool discovery
The scraper queries the local Bor node for historical factory contract creation events — PairCreated for Uniswap V2, PoolCreated for Uniswap V3. Factory addresses and event signatures are stored in a pool_types database table rather than hardcoded, so adding support for a new DEX requires only inserting a new row.
On each run, the scraper resumes from the highest previously recorded block number. For every matched creation log, it extracts token addresses from the event topics and decodes the ABI data to find the deployed pool address — accounting for protocol-specific byte padding (12-byte offset for V2, 44-byte offset for V3). It then issues synchronous RPC calls to fetch the symbol and decimals for both underlying tokens, skipping and logging any malformed or non-compliant ERC-20 tokens. Pools are written using INSERT OR IGNORE, ensuring overlapping runs never corrupt existing records.
Phase 2: activity scoring and prioritization
The scraper executes a secondary pass that queries all Swap events emitted across the entire network over a rolling 5-day lookback window (calculated assuming a 2.1-second average block time). It tallies the swap count for every discovered pool and updates a txns column in the database.
Scoring on a rolling 5-day window rather than lifetime transaction count ensures the system prioritizes pools with current economic activity rather than historical dominance. When the Rust indexer boots, it executes an ORDER BY txns DESC query, loading only the most actively traded pools into memory and ignoring all pools with zero recent swaps.
3. Rust block indexer
The indexer is a custom Rust application responsible for tracking the real-time state of the chosen AMM pools. It subscribes to the local node’s block stream and processes every new block within a hard 2-second budget — Polygon’s approximate block interval.
Startup and database loading
At startup, the indexer opens a WebSocket connection to the local Bor node’s eth_subscribe newHeads endpoint. Once the stream is live, it queries the local SQLite database for the top N most active pools (joined with token metadata, sorted by txns DESC). Token descriptors are interned using Arc<Token> — if dozens of pools share a common token (WETH, USDC), they all point to a single heap allocation rather than duplicating the struct.
Pool abstraction and data model
The core data structure is a HashMap<Address, Box<dyn Pool>> mapping each on-chain contract address to a heap-allocated trait object. The Pool trait defines a uniform interface across all AMM architectures:
populate()— async method that performs the initial RPC calls to fetch current on-chain statehandle_event()— synchronous mutator that accepts a rawLogand applies the specific reserve changesprice()— getter that derives the current decimal-adjusted mid-priceequal()— diagnostic method for state validation against a fresh on-chain fetch
Dynamic dispatch via trait objects means all pool types live in a single collection and update through the same handle_event() call — no match arms on pool type in the hot path.
Protocol-specific state initialization
Each AMM protocol manages state differently, so populate() behaves differently per pool type:
Uniswap V2 — calls getReserves() to retrieve the 112-bit reserve balances, converts them into native Rust u128 integers. Fee is statically hardcoded to 0.3%.
Uniswap V3 (concentrated liquidity) — requires a more complex sequence. The indexer fetches the current sqrtPriceX96 and tick from slot0(), the fee(), tick granularity from tickSpacing(), and the active liquidity(). It then computes the current 256-bit word index for the active tick and iterates over a compressed tick bitmap for ±10 words. For every initialized tick discovered in this window, it fetches the liquidityNet delta and stores it in a HashMap<i32, i128>.
Algebra V3 / QuickSwap — similar to Uniswap V3 but highly optimized. Uses a single globalState() call to fetch price, tick, and the current dynamic fee tier simultaneously. Fixed tick spacing of 1.
Pool initialization is fully serialized to respect RPC rate limits — startup time scales linearly with pool count.
Main processing loop
For every new block header from the WebSocket stream, the indexer creates a block filter for that specific block number and issues a single eth_getLogs call — retrieving all swap/sync events emitted in that block across the entire network. The system applies no address whitelist to this call: it retrieves all logs, iterates them in O(N), and performs an O(1) lookup against the HashMap to see if the emitting address is tracked. Unknown addresses are silently discarded. Filtering in memory this way is faster than filtering the RPC call itself, and the O(1) dispatch makes the per-log cost negligible even with the wider unfiltered sweep.
Indexer module flow: main.rs awaits each block and calls index_logs on indexer.rs, which updates the pool index and dispatches each matching log through mod.rs to its protocol-specific handler. Each handler owns its own state store — reserves for V2, sqrtP + liquidity for V3 and Algebra.
4. Latency benchmarking
The indexer includes a compile-time profiling framework behind a feature gate (--features log_latency). This ensures all timestamping and logging code is entirely excluded from the production binary unless explicitly enabled — zero overhead in production.
The profiling system captures five sequential timestamps per block using SystemTime::now(): block produced (from the header), header received, request dispatched, logs received, and state updated. These produce four derived metrics — block reception latency, log fetch latency, state update latency, and end-to-end latency.
By toggling a single compile-time flag, the WebSocket connection switches between the local Bor node and the Alchemy RPC endpoint. Because both expose identical JSON-RPC interfaces — eth_subscribe for headers, eth_getLogs for events — the indexer executes identical code against both, so any measured delta is attributable purely to infrastructure. The benchmark ran continuously for 730 blocks (~25 minutes) against both endpoints.
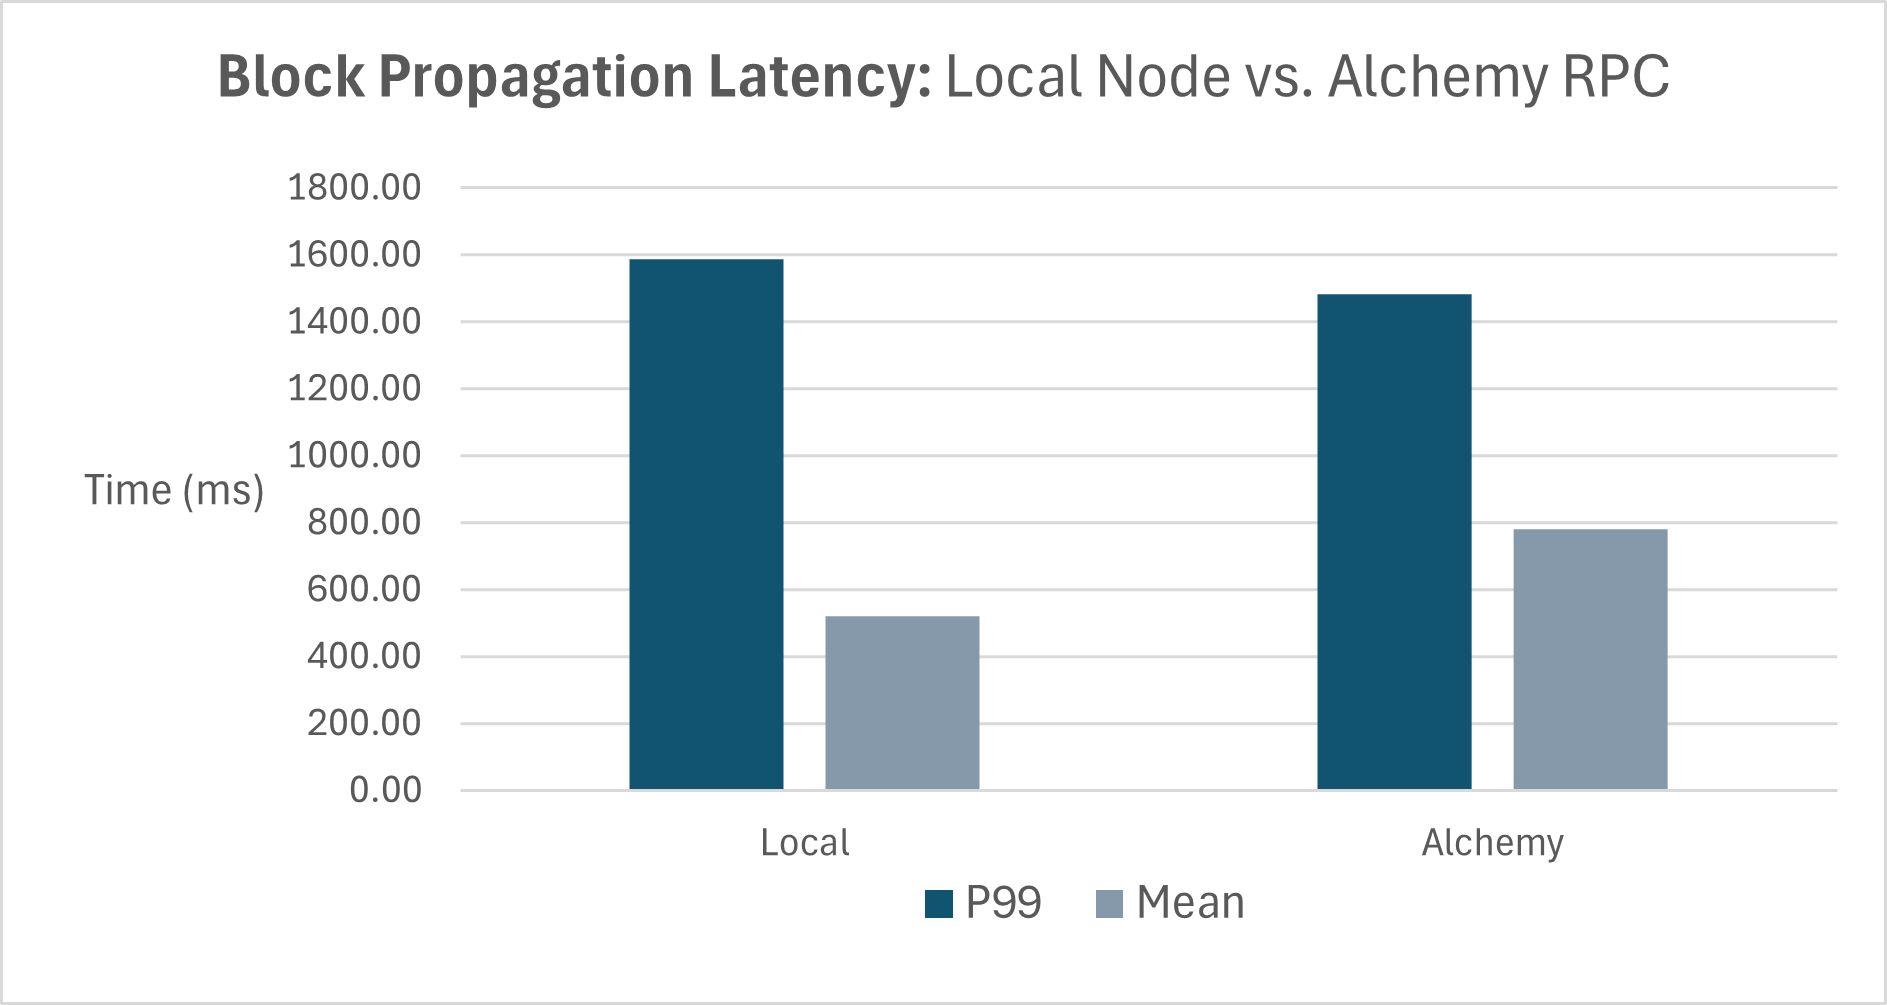
Block reception latency: median 413 ms local vs. 674 ms Alchemy (1.6× faster). At P99, both converge to ~1,490–1,590 ms — tail latency here is governed by Polygon's own P2P propagation variance, not infrastructure choice.
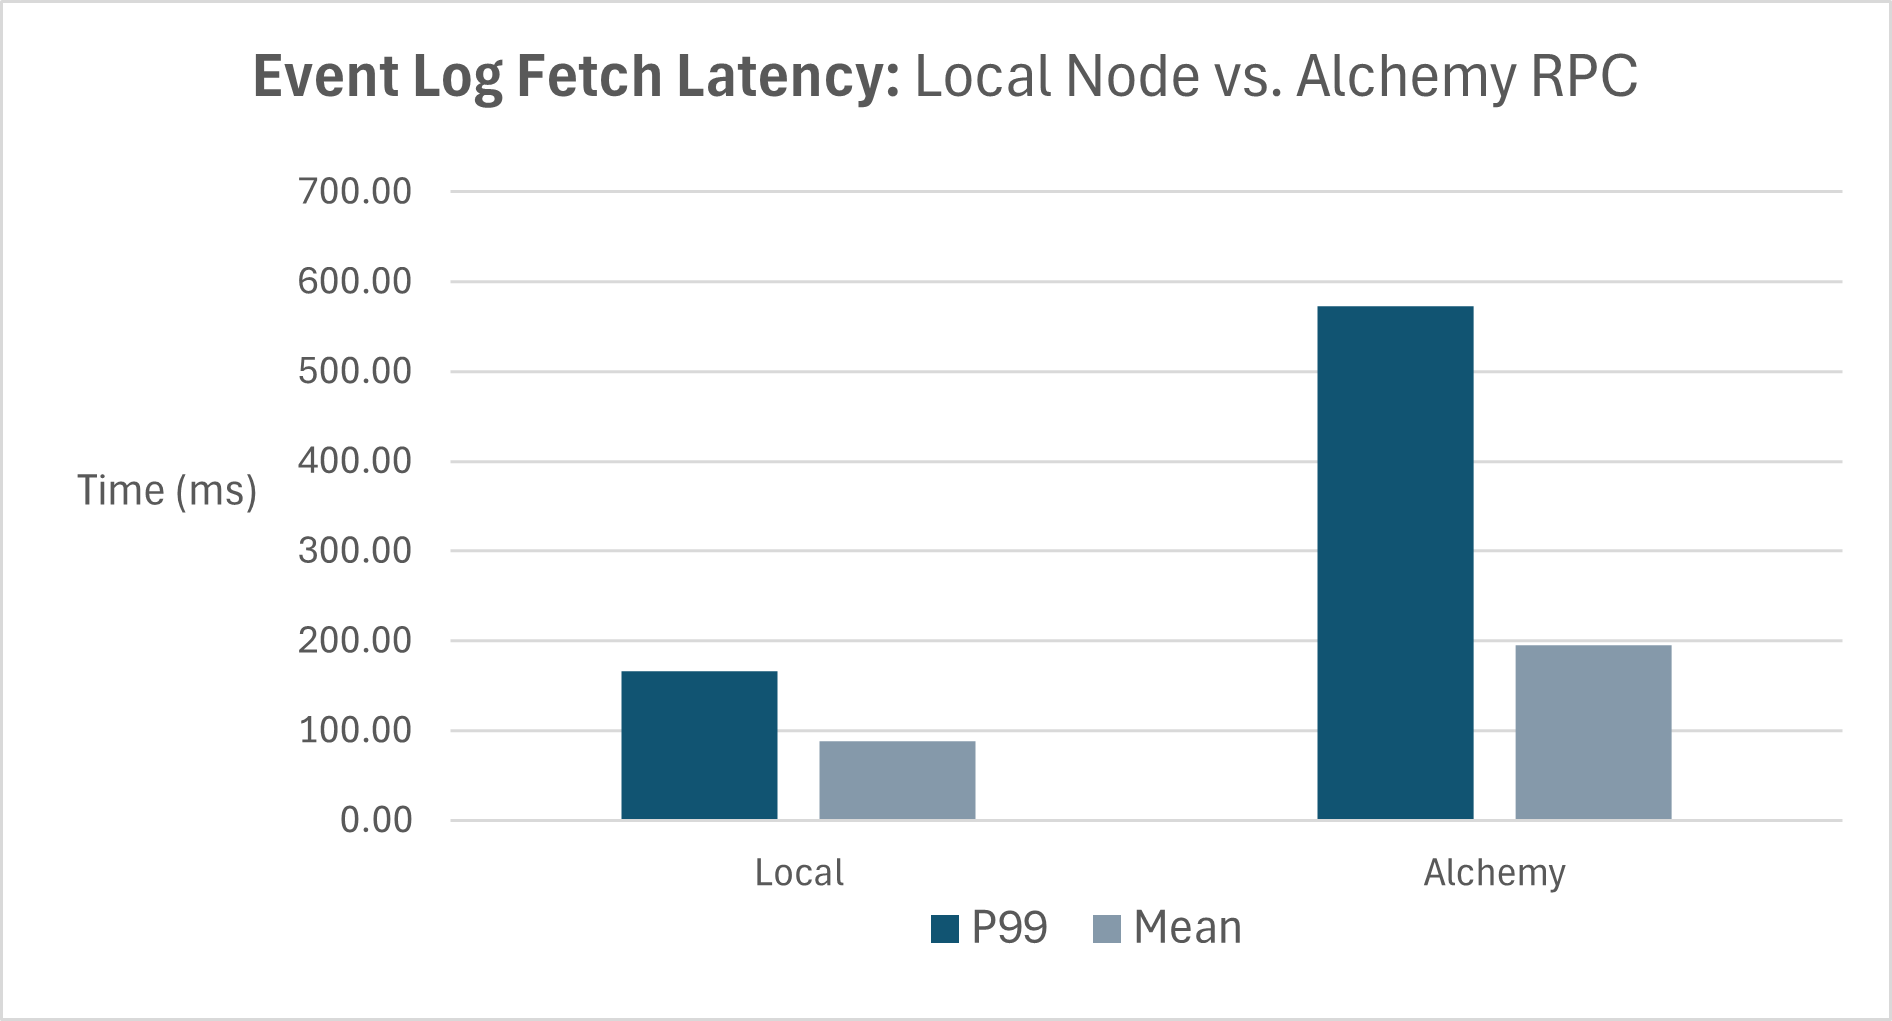
eth_getLogs latency: median 83 ms local vs. 166 ms Alchemy (2.0×), widening to 161 ms vs. 573 ms at P99 (3.6×). Standard deviation: 29 ms local vs. 96 ms Alchemy — the local node is both faster and far more consistent.
State update latency — pure Rust log decoding and in-memory HashMap mutation — held at a median of 1 ms (P99: 2 ms) regardless of endpoint, confirming the entire gain comes from the network layer and that indexer processing itself is not a meaningful fraction of the 2-second block budget.
Results: end-to-end pipeline
| Setup | Mean | Median | P95 | P99 |
|---|---|---|---|---|
| Local node | 610 ms | 496 ms | 1,487 ms | 1,754 ms |
| Alchemy RPC | 975 ms | 840 ms | 1,820 ms | 2,056 ms |
| Savings | 365 ms | 344 ms | 333 ms | 302 ms |
From block production to a completed in-memory state update, the local stack achieves a median of 496 ms against 840 ms for Alchemy — a 1.7× improvement and a 344 ms head start on every block over any competing system still reading through a third-party provider. Runs were conducted sequentially rather than concurrently, so the two setups saw slightly different blocks and network conditions; the 730-block sample size and the absence of any observed anomalous network events over that window keep this confound small.
5. Accuracy oracle
A fast indexer that silently misses events or applies them incorrectly is worse than a slow one: the detection engine evaluates routes against stale prices that no longer exist on-chain, generating phantom opportunities that revert on execution.
After processing all logs for a block, the indexer identifies which pools were touched by at least one relevant event. From this set, a random sample of up to num_accuracy_samples pools is selected. For each sampled pool, the indexer constructs a second, independent pool object by issuing fresh RPC calls directly to the blockchain (slot0(), reserves(), or globalState() depending on pool type), and compares the two field-by-field using the pool’s equal() method. Any discrepancy increments the incorrect-state counter for that block. This runs continuously in production as a live correctness signal, independent of the latency measurement path.
What each pool type checks:
- V2 —
reserve0,reserve1,fee. A failure implies a droppedSyncevent. - V3 — additionally checks
sqrt_p(fromslot0()), currenttick, activeliquidity, and the entireliquidity_netHashMap.sqrt_pcatches swap-level drift;liquidity_netcatches errors inMint/Burnprocessing. - Algebra V3 — same logic as V3, substituting
globalState()forslot0()andtickTable()fortickBitmap().
Results
Accuracy was benchmarked over a separate 450-block window (~15 minutes), with num_accuracy_samples set to 50 so that every pool touched in a block gets checked. The indexer held a mean accuracy above 99% per block, at 100% for the large majority of blocks, with failures appearing as isolated spikes rather than sustained drift. The single worst block, 85105385, saw 14 of 19 sampled pools fail (26% accuracy) — outside that one event, no block fell below 60%.
Cross-referencing the failure log against the accuracy data attributed every failure in the window to five specific pools:
Four of the five failing pools are Uniswap V3, with failures concentrated around Mint, Burn, and Collect events — consistent with the theory that these specific contracts were modified by their deployers to skim reserves, which by construction the indexer can’t model since it assumes the unmodified reference implementation. These pools should be filtered out rather than chased with more decoding logic.
One systematic quirk worth noting: after a missed event, subsequent blocks continue to register non-zero misses on the same pool even though no further event was actually dropped — the in-memory state simply stays wrong until the next real event overwrites it. That’s a real correctness bug rather than a benchmarking artifact, and closing it (re-fetching the pool immediately on a detected mismatch, instead of waiting for the next event) is a clear next step toward the 100% target.
6. Arbitrage detection and execution
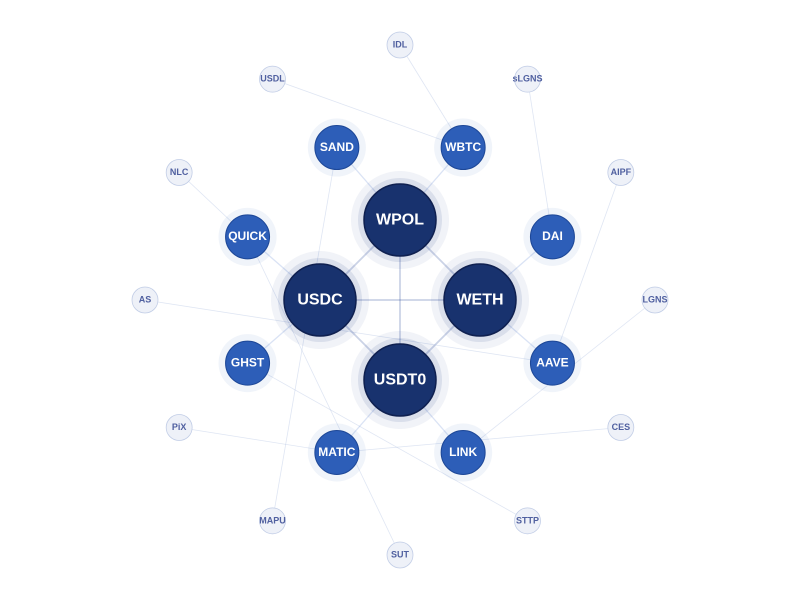
The detection algorithm searches the in-memory pool graph for profitable multi-hop cycles after every state update. The graph is a token-centric view: nodes are tokens, edges are pools. A profitable arbitrage is a cycle in this graph where traversing the edges in sequence yields more of the starting token than you put in.
Token graph across tracked Polygon pools. Hub tokens (USDC, WETH, USDT0, WPOL) connect to most pools and anchor the majority of detected arbitrage cycles; peripheral tokens sit one or two edges out, contributing far fewer routes.
Optimal route sizing
Because every market’s output is a deterministic function of its reserves and fee, the full set of markets can be modelled as a set of trades each one will accept. Summing the acceptable trades across every tracked market gives a single optimization problem: find the net trade ψ across all markets that maximizes utility
U(ψ) = cᵀψ − I(ψ ≥ 0)
where I is an indicator that is ∞ if any token is net tendered to the market and 0 otherwise, and the coefficients c are proportional to the value of each token the algorithm already holds (zero for tokens it doesn’t). This makes the utility −∞ for any trade that requires capital the system doesn’t have, and linear in tokens received otherwise — so the resulting optimal ψ always decodes into a cycle that starts and ends on a token the algorithm holds. This is a convex optimization problem, solved efficiently with the LBFGS-B optimizer rather than an exhaustive search over cycles, which is what lets the detection engine scale past simple fixed-length loops to the full pool graph on every block.
Execution contract architecture
Execution contract call chain on Polygon PoS. The ExecutorRouter receives an encoded multi-hop route and delegates each hop to the matching executor, which calls the corresponding on-chain DEX router. All hops compose atomically within a single transaction.
Execution contracts were deployed to Polygon PoS mainnet (chain ID 137) using a Foundry DeployAll script. Each specialized executor conforms to a shared IExecutor-style interface so the router can compose heterogeneous pool types within one atomic route: a single transaction can, for instance, buy on a Uniswap V2 pool and sell on a QuickSwap Algebra pool. The transaction enforces its own profitability on-chain, at the contract level, independent of anything the off-chain detection engine believed to be true:
require(amountOut > amountIn, "Unprofitable");
If market conditions change between route detection and block inclusion — because a competing transaction consumed the same opportunity first — the contract reverts and the caller loses only the gas cost of the failed call. Contracts are access-restricted to the team’s operator wallet to prevent front-running of the execution contract itself. Transactions are submitted through the local node’s eth_sendRawTransaction endpoint, so there are zero external RPC hops at the moment of submission — the same advantage the rest of the pipeline was built around.
What’s next
The results confirm self-hosting the data path produces a measurable, stacking advantage — lower latency, more consistent latency, and a state model the team can actually audit for correctness. The next highest-leverage work, in priority order:
- Mempool monitoring. Large pending swaps are visible before block inclusion. Watching them would let the system anticipate the resulting pool-state change and have a transaction ready the moment the triggering swap confirms — event-driven back-running instead of block-level scanning. This was the stretch goal for this phase and remains the single most impactful unexplored latency lever.
- Co-locate with the validator network. Moving the server into a data center with a low-latency path to Polygon block producers removes the one remaining bottleneck no software change can touch: P2P propagation time. Standard practice among professional MEV searchers, and the highest-priority infrastructure investment for the next phase.
- Separate the indexer and detection engine onto dedicated hardware. They currently share CPU on one machine; under high block activity, compute contention can delay state updates. Splitting them across a low-latency IPC channel would let each be tuned independently.
- Optimize execution contract gas consumption. The contracts have not been gas-optimized beyond correctness. Lower gas improves profitability on marginal opportunities and can improve transaction ordering priority in blocks where producers order by effective gas price.